Visual AI agents: three kinds and the layer that decides
Three distinct products are marketed as visual AI agents. A fourth item often bundled with them isn’t a product at all, it’s an approval layer. A visual AI agent is an AI agent built around a visual channel rather than text alone. It perceives and interacts with a graphical interface, reading screenshots or rendered pages instead of structured data or APIs, and acts on what it “sees”, typically by moving a cursor, clicking, typing, or scrolling the way a human would use a screen. That visual channel might be a camera feed, an animated presenter, or a drag-and-drop canvas used to assemble the agent.
The fourth item is an approval layer. It is where a proposed action sits while someone decides whether to let it through. This is where the rubber meets the road and remains a critical phase in any AI agent process. This makes it a layer rather than a category, and the first three may each need one. Which one you buy determines who signs off, what the evaluation tests, and what a mistake costs.
What are visual AI agents, and what does the label cover?
Plainly stated, a visual AI agent is an AI agent whose defining feature is a visual channel rather than text alone. The label covers three distinct products: agents that perceive through cameras, agents presented as animated avatars, and agents assembled on a drag-and-drop canvas. An approval layer is sold alongside them and is a different kind of thing.
Vendors rarely do this sorting for you. Two products both described as visual agents can share a comparison sheet even though one opens with a talking face and the other opens with an approval queue. A procurement team working from feature lists will not catch the gap until implementation, when the accountable owner turns out to be a department that never saw the demo. By then, it’s too late, and the contract is signed.
The last row is the one that moves the decision out of the operating team. Perception, presentation, and assembly can all be judged by the people who will run the agent day to day. Who answers for a wrong action is a different question, and it usually has a different name attached to it. That name is rarely in the room for the demo.
Sort visual AI agents by what they run without a human
Sort candidates by what the agent can execute without a person in the loop. A camera that flags a torn label and a fraud agent that freezes an account both perceive and both act, and only one of them moves money. Consequence, reversibility, and volume decide how much review a deployment needs, not how the interface looks.
This is harder than it sounds, because vendor language works against it. Gartner’s June 2025 assessment named the practice of agent washing, meaning the rebranding of existing assistants, robotic process automation, and chatbots without substantial agentic capability. It put the number of genuinely agentic vendors at about 130, out of thousands marketing themselves that way. The label is doing work the product is not.
Put the question to a demo directly. Ask what happens between the moment the agent decides and the moment the action lands in a production system. If the answer is nothing, you are buying an autonomous system whose interface happens to be visual. The screen you should be evaluating does not exist yet.
Reversibility is the second variable, and it separates agents that look identical on paper. An action that can be undone with one click tolerates a much looser review than one that reaches a customer, a regulator, or a ledger. Two agents with identical accuracy can need completely different oversight because one writes to a draft and the other sends. Accuracy is not the variable.
Volume is the third variable. It also quietly kills approval layers. An agent proposing twelve actions a day can have each one read carefully. The same agent at four thousand a day cannot. No amount of interface design fixes that.
That leaves two honest options: narrow what the agent can touch without approval, or accept that most of its output runs unreviewed and design the sampling accordingly. Teams that never make the choice end up with the second one anyway, discovered during an incident review rather than decided in advance.
Perception agents: seeing the defect is the easy half
A camera on a packaging line can register a torn label before the belt advances, and whether it saw the tear is the least interesting question about it. What matters is what happens next. A system that only classifies is a vision model with a dashboard attached, while one that pauses the line, routes the unit for inspection, and notifies a supervisor is running an action loop.
Pilot evaluation turns almost entirely on operating conditions. Detection accuracy under clean studio lighting says little about a facility with dust, reflections, shift changes, and camera mounts that drift when someone knocks them. The honest test is whether the system separates a genuine defect from an acceptable variation at the speed the line runs. Demos are shot under clean conditions.
A perception agent fails in two directions, and they cost different amounts. A missed defect reaches a customer. Scrapping a good unit costs material and slows the line. A specification usually optimizes against one of the two without saying so, and a demo rarely reveals which, so the approval screen has to make that choice visible.
Production adds a question the pilot never asks, which is whether a person sees the agent’s call before the line stops. Holding a batch has a cost, and so does letting a defective one through. The supervisor weighing those two costs in the moment needs more than a box drawn around a label.
That is why a perception agent with authority to stop a line needs an approval screen, not just a detection feed. A reviewer has to see the detected condition in words, the action being recommended, and how confident the system is that the condition is real. They are answering two questions at once: whether the defect is genuine, and whether stopping the line is proportionate.
Avatars: the version most vendors are selling
Avatar agents use the visual channel for presentation rather than perception, pairing a conversational system with a face, synchronized speech, and expressive behavior. That changes how a customer experiences the interaction and changes nothing about how well the system reads data, follows policy, or drives the applications behind it.
Search the term today and much of what comes back is avatars. D-ID, among the most visible vendors in that space, markets animated presenters under the agent label, and it is not alone. The category is real and the products work.
The trouble is that an avatar is a claim about presentation, and buyers routinely read it as a claim about capability. Presentation and capability are not the same purchase, and the gap between them is where budget gets committed to the wrong thing.
Consider a lending assistant with an on-screen presenter. It walks an applicant through the steps, answers questions about documents, and pre-fills parts of a form. All of that is useful. None of it needs an approval layer.
Now give the same assistant the ability to quote a rate, waive a fee, or set an eligibility flag. Nothing about the avatar changed, but the consequence did, and a confident delivery is doing work it was never designed to do. Warmth reads as certainty to most users, which becomes a design problem the moment the system can commit the company to something.
That second assistant needs an approval layer, and the avatar has nothing to do with providing one. The presenter can front the conversation with the customer. A plainer screen gives an accountable employee what they need to approve, change, or reject the proposal. Vendors who sell the first and imply the second are why procurement teams end up surprised.
Build canvases: seeing the workflow is not seeing the decision
Canvas builders are the third use of the word visual, and this one describes how the agent gets assembled rather than how it behaves. A canvas lets a team wire up triggers, tool calls, conditions, data sources, and escalation paths without writing the orchestration by hand. It also produces a diagram that product managers, engineers, and operations leads can argue about in one room.
The mistake it invites is treating the diagram as a record of what happened. A canvas shows how the agent was designed to behave, which is not the same as what it did. It cannot tell you what the agent sent to a particular customer on a particular afternoon, which policy fired, or whether anyone intervened. Design is not evidence.
That gap shows up as an audit you cannot answer. A regulator or a customer asks why a decision went the way it did, and the team can produce the workflow that was supposed to run rather than the decision that ran. Rebuilding it from logs afterward means reconstructing a decision from data that was never designed to explain one. That work lands on whoever is least able to refuse it.
The gap cuts both ways. A canvas-built support agent that drafts customer replies needs a screen where a person approves the reply before it sends, not a log of what went out overnight. Support leads need both screens, and the workflow editor is neither of them. If a vendor answers a question about oversight by showing you the canvas again, they have neither.
The approval layer: where the money is
An approval layer is the review step where an agent’s proposed action waits for a person who can stop it. Its screen names the action, the evidence behind it, the policy that triggered it, and the controls to approve, modify, or reject. It is a layer the other three kinds may each need rather than a fourth kind of agent.
It matters when an agent can create financial, legal, safety, or customer-facing consequences: fraud review, procurement, claims, contract handling, pricing, account administration, and outbound customer communication. It also gets the least marketing, because an approval queue does not demo as well as a talking head.
Take a fraud agent weighing transaction value, device signals, account history, and location. It might recommend allowing, challenging, or blocking. Configured more aggressively, it holds the transfer and freezes the account while the customer is still standing at the counter. The approval screen is the only thing between the recommendation and that outcome.
A usable version of that screen leads with the recommendation in plain language rather than with supporting data. It says the system wants to hold this transfer because the device is new, the amount is unusual, and the location does not match recent activity. Naming the policy and the uncertainty comes next, then the controls.
None of that requires exposing the model’s internal operations. A reviewer does not need a trace of every intermediate computation. Handing them one buries the few facts that would change their answer. What they need is the evidence bearing on the decision in front of them, and more detail past that point buys less oversight rather than more.
Regulation has converged on roughly the same standard. Article 14 of the EU AI Act requires high-risk systems to ship with human-machine interface tools that let an assigned person oversee them effectively. That person must understand the system’s limits, stay aware of automation bias, interpret the output, override it, and interrupt operation through a stop button or a similar procedure. The law is describing an interface.
Those duties attach to high-risk systems inside the Act’s scope, not to every agent a company deploys. They still describe a reasonable design floor. NIST’s AI Risk Management Framework points the same way, treating how often humans overrule an AI system, and why, as something worth recording in deployed systems.
What belongs on screen before someone approves
A reviewer needs four things before approving an agent’s action. Those are the proposed change in plain language, the evidence and policy behind it, an honest signal of how uncertain the system is, and whether the action can be undone. Everything else on that screen competes for attention with those four.
Matching oversight to consequence is what keeps the queue usable. Requiring human approval for every low-risk action produces rubber-stamping, and a reviewer who approves everything is worse than no reviewer, because the audit trail now records a human decision that never happened.
- The action preview. Plain language, not a JSON payload: the agent will cancel the duplicate order, refund the difference, update the customer record, and notify the account owner.
- Evidence and the policy that fired. A short policy label and risk category stop reviewers guessing why an item reached them at all.
- Calibrated uncertainty. A bare number invents precision. A score of 87 percent tells a reviewer nothing on its own, because they cannot see how it was measured, which test set it came from, or whether this case sits inside the range the system was evaluated on. The interface has to say what the signal measures and where it stops being reliable. A reviewer who cannot tell a well-calibrated score from a decorative one ends up trusting all of them or none of them.
- Reversibility. Whether approval can be undone, for how long, whether a downstream system has already acted, and who owns the recovery.
An approval layer costs throughput, and pretending otherwise is how it gets cut in month three. Every action routed to a person waits for that person. Good design decides where that wait is worth paying rather than trying to remove it.
Spending that cost evenly is the common error. Review every action at the same depth and the dangerous ones get skimmed while the harmless ones get read at all. That costs you twice. The highest-consequence actions deserve the slowest, most deliberate look on the screen. Everything else needs a path that does not route through a human.
Two behaviors sit underneath those four requirements. An agent needs a defined response for situations outside its approved scope, so that missing information or conflicting instructions produce a routed case rather than a confident guess. It also needs graduated autonomy, so routine ticket categorization runs unattended while anything touching a legal commitment stops for a person.
Graduated autonomy is easier to describe than to set. The threshold that decides what runs unattended is a business decision wearing a technical costume, and it belongs to whoever owns the consequence rather than to the team tuning the model. Teams that skip that conversation usually discover the threshold was set by whoever configured the system first.
Measure the approval layer on its own terms once it is live. Approval latency, override rate, and audit retrieval time only mean something read together, because a low override rate can signal accurate recommendations or a queue nobody is reading closely. The interaction patterns underneath all of this are covered in our guide to designing UI for AI agents.
CyberDefend and OptivionAI: evidence next to the decision
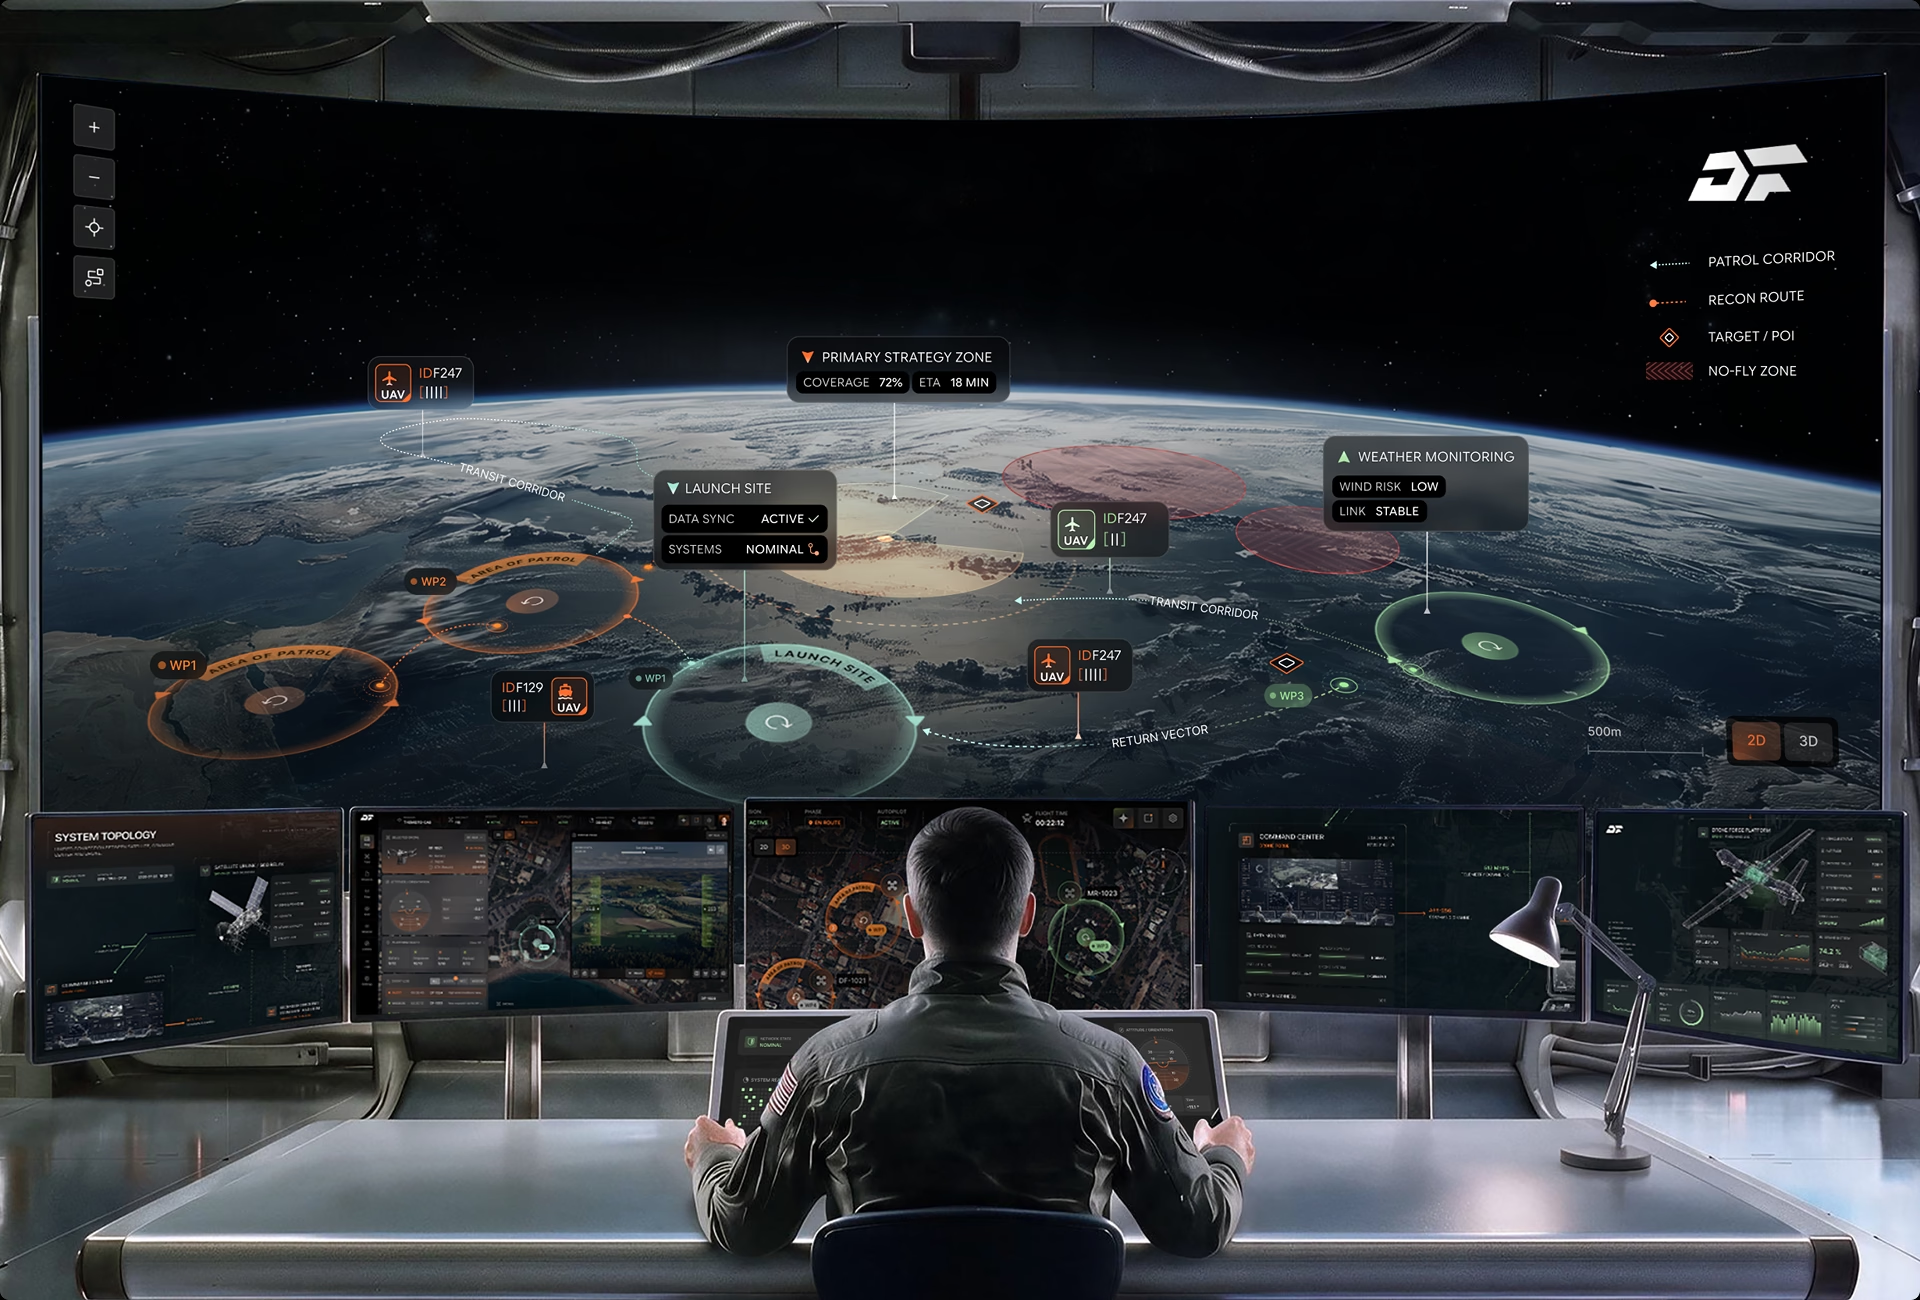
A collision-avoidance decision cannot be unwound after the fact, which is the kind of constraint the CyberDefend dashboard was built around. It gives space operations teams satellite health, orbital tracking, and threat detection in one view, with machine learning analyzing orbital data to predict conflicts and recommend a response before a situation becomes critical. That is an agent proposing an action with real consequence attached. Somebody has to say yes to it.
The part that matters here is what sits next to the recommendation. CyberDefend surfaces flagged events alongside their domain-specific activity logs, so an operator sees the triggered alert and the exact sequence of actions that preceded it in the same place. The evidence and the proposal arrive together rather than in two systems. Most tools make the operator go and find one of them.
Ordering does the other half of the job. The OptivionAI network operations platform, which we designed for telecom incident management, sorts a city by exception, so a degraded sector pulls the eye while healthy sites recede into the map. It also settles who is looking at which version of events: whoever opens an incident, on a roof or at the operations desk, reads one record rather than two.
Both carry the same lesson into agents with more authority. A reviewer does not need everything the system knows. They need the proposal, the evidence that produced it, and confidence that the person who owns the consequence is reading the same record.
What to ask before a vendor reaches a shortlist
Ask four questions before a vendor reaches a shortlist. What does the agent perceive, what can it execute without approval, who inside your company answers for that action, and how does a reviewer stop it once it has started? A vendor fluent on the first and vague on the third is selling perception rather than oversight.
The third question reorganizes the buying group. If the honest answer is the head of risk or the CFO, the operations team alone can’t run the evaluation. The demo that impressed the product organization is not the screen that decides the purchase.
Naming the kind you are buying is only half of it. The approval layer has to be on the table during the same evaluation, because a perception agent, an avatar, and a canvas-built workflow can each reach the point of acting on their own. Few of them ship with an approval layer that matches your policy. A generic approval node in a vendor’s builder is not the screen an accountable reviewer needs.
Ask when the approval layer gets specified. A layer designed alongside the agent is a design problem. The same layer requested after the agent is in production is a design problem plus a data problem, because the evidence a reviewer needs on screen is often not being captured yet.
When the agent will take actions carrying financial, legal, or customer-facing weight, the approval layer is the product. It should be specified before the agent gets access to anything hard to reverse. Designing that layer is what visual agent design covers, and it belongs in scope alongside the agent rather than after it.
Start with the consequence, not the demo
The visual AI agents label will keep covering three unrelated products and one layer for as long as it sells, so the sorting is yours to do. Work out what the agent can execute without a person, then find whoever answers for that action. Build the evaluation around that person’s screen, because every remaining question about the interface follows from those two answers. Start there, not at the demo.
Frequently asked questions
What is the difference between visual AI agents and vision AI agents?
Vision AI agents use cameras, video, screen recordings, or LiDAR to perceive an environment and act on what they detect. The visual label is broader and looser, stretching across vision systems, avatar presenters, and drag-and-drop builders, and vendors also use it for the approval screens those agents need. When a vendor says visual rather than vision, ask which one they mean.
How do visual AI agents differ from RPA or workflow automation?
RPA follows deterministic rules along a path defined in advance, so the workflow itself is the unit you review. Agents choose tools, sequence their own actions, and respond to conditions at run time, which makes each proposed action the thing that needs reviewing. Where a deployment combines both, the agentic portion is where approval controls and audit trails earn their cost.
Does an avatar agent need a separate approval layer?
Avatar agents need an approval layer as soon as they can change a record, set a price, or commit the company to anything. The avatar itself is a presentation choice and carries no oversight function. An assistant that only explains a process and answers questions does not need one.
What should a buyer ask a vendor to prove an agent is reviewable?
Ask the vendor to open a real approval screen on a live case rather than a slide. It should state the proposed action in plain language, name the policy that triggered it, show calibrated uncertainty, and offer controls to approve, modify, reject, or escalate. A vendor who cannot produce that screen on request does not have one in production.
Who should evaluate visual AI agents inside a company?
The evaluation group depends on which kind is being bought, which is why the category confusion is expensive. Perception agents are judged by operations and quality, avatars by customer experience, and canvases by engineering and product. The approval layer belongs to risk, compliance, or finance, and because nobody treats it as a separate purchase, that group is the one most often missing from the first demo.
Should an approval layer be designed in-house or with a design partner?
In-house teams build approval layers well once they have shipped one and have research access to the reviewers who use it daily. First attempts go wrong in predictable places, usually by exposing model internals instead of decision-relevant evidence, or by routing so much to humans that reviewers stop reading. A partner earns its cost mainly on that first build, where the patterns get set and later interfaces inherit them.
Do EU AI Act human oversight rules apply to every AI agent?
Article 14 of the EU AI Act applies to high-risk AI systems inside the Act’s scope, not to every AI agent a company deploys. Its requirements still work as a design floor for any agent with consequential authority, covering system limits, automation bias, override, and safe interruption through a stop button or similar procedure. Treating them as a baseline is easier than retrofitting oversight after an incident.